ANOVA GLM
Introduction
H2O ANOVA GLM is used to calculate Type III SS (sum of squares) which is used to investigate the contributions of individual predictors and their interactions to a model. Predictors or interactions with negligible contributions to the model will have high p-values while those with more contributions will have low p-values. The term predictors refers to individual predictors or interactions of predictors.
Since ANOVA GLM is mainly used to investigate the contribution of each predictor or interaction, scoring, MOJO, and cross-validation are not supported.
Defining an ANOVA GLM model
Parameters are optional unless specified as required. ANOVA GLM shares many GLM parameters.
Algorithm-specific parameters
- highest_interaction_term: This option limits the number of interaction terms (that is,
2means interaction between 2 columns only,3for three columns, and so on). This option defaults to2. - nparallelism: Set the number of models to build in parallel (adjust according to your system). This option defaults to
4. - save_transformed_framekeys: Enable this option to save the keys of transformed predictors and interaction columns. This option defaults to
False(disabled). - type: Refer to the SS type 1, 2, 3, or 4. H2O-3 Secure currently only supports type 3.
Common parameters
-
balance_classes: (Applicable only for classification) Specify whether to oversample the minority classes to balance the class distribution. This option can increase the data frame size. Majority classes can be undersampled to satisfy the
max_after_balance_sizeparameter. This option defaults toFalse(disabled). -
class_sampling_factors: (Applicable only if
balance_classes=True) Specify the per-class (in lexicographical order) over/under-sampling ratios. By default, these ratios are automatically computed during training to obtain the class balance. -
early_stopping: Specify whether to stop early when there is no more relative improvement on the training or validation set. This option defaults to
False(disabled). -
ignore_const_cols: Specify whether to ignore constant training columns since no information can be gained from them. This option defaults to
True(enabled). -
ignored_columns: (Python only) Specify the column or columns to be excluded from the model.
-
max_after_balance_size: (Applicable only if
balance_classes=True) Specify the maximum relative size of the training data after balancing class counts. The value can be > 1 and defaults to5.0. -
max_iterations: Specify the number of training iterations. This option defaults to
0. -
max_runtime_secs: Maximum allowed runtime in seconds for model training. This option defaults to
0(unlimited). -
missing_values_handling: Specify how to handle missing values. One of:
Skip,MeanImputation(default), orPlugValues. -
model_id: Specify a custom name for the model to use as a reference. By default, H2O automatically generates a destination key.
-
offset_column: Specify a column to use as the offset. This will be added to the combination of columns before applying the link function.
-
score_each_iteration: Specify whether to score during each iteration of the model training. This option is set to
False(disabled) by default. -
seed: Specify the random number generator (RNG) seed for algorithm components dependent on randomization. The seed is consistent for each H2O instance so that you can create models with the same starting conditions in alternative configurations. This option defaults to
-1(time-based random number). -
standardize: Specify whether to standardize the numeric columns to have a mean of zero and unit variance. This option defaults to
True(enabled). -
stopping_metric: Specify the metric to use for early stopping. The available options are:
AUTO(default): (This defaults tologlossfor classification anddeviancefor regression)devianceloglossMSERMSEMAERMSLEAUC(area under the ROC curve)AUCPR(area under the Precision-Recall curve)lift_top_groupmisclassificationmean_per_class_error
-
stopping_rounds: Stops training when the option selected for
stopping_metricdoesn't improve for the specified number of training rounds, based on a simple moving average. This option defaults to0(no early stopping). The metric is computed on the validation data (if provided); otherwise, training data is used. -
stopping_tolerance: Specify the relative tolerance for the metric-based stopping to stop training if the improvement is less than this value. This option defaults to
0.001. -
training_frame: Required Specify the dataset used to build the model.
-
weights_column: Specify a column to use for the observation weights, which are used for bias correction. The specified
weights_columnmust be included in the specifiedtraining_frame.Python only: To use a weights column when passing an H2OFrame to
xinstead of a list of column names, the specifiedtraining_framemust contain the specifiedweights_column.Note: Weights are per-row observation weights and do not increase the size of the data frame. This is typically the number of times a row is repeated, but non-integer values are supported as well. During training, rows with higher weights matter more, due to the larger loss function pre-factor.
-
x: Specify a vector containing the names or indices of the predictor variables to use when building the model. If
xis missing, then all columns exceptyare used. -
y: Required Specify the column to use as the dependent variable. The data can be numeric or categorical.
Type III SS
To demonstrate what Type III SS is and how it is implemented, here is an example of regression with two categorical predictors:
- note: This algorithm will support multiple categorical/numerical columns and other families as well; we just need to replace the SS with the residual deviance for other families.
SS (sum of squares)
In Analysis of Variance (ANOVA), the partition of the response variable sum of squares in a linear model is described as "explained" and "unexplained" components. Consider a dataset generated by
where
- is the response variable;
- are the predictors;
- are the system parameters;
- .
The total sum of squares of this dataset can be decomposed as follows:
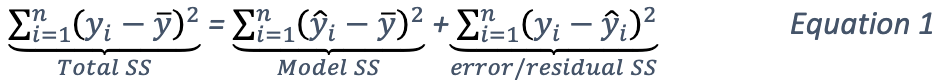
where
- ;
- .
Generally, addition of a new predictor to a model will increase the model SS and reduce the error or residual SS.
The model SS by itself is not useful. However, if you have multiple models, the difference in model SS between two models can be used to determine model performance gain/loss.
Type III SS calculation
The Type III SS calculation can be illustrated using two predictors (C,R). Let
- denote the model sum of squares for GLM with predictors C,R and the interaction of C and R;
- denote the model sum of squares for GLM with predictors C,R only;
- denote the model sum of squares for GLM with predictors R and the interaction of C and R;
- denote the model sum of squares for GLM with predictors C and the interaction of C and R.
Type III SS calculation refers to the incremental sum of squares by taking the difference between the model sum of squares for alternative models:
- ;
- ;
- .
The second part of the equations can be derived from Equation 1. Note that the is just the residual deviance of the models.
The same procedure applies if there are more predictors. In general, to calculate the Type III SS, we build the model with all the predictors and all the predictor interactions and compare the full model to taking out either one predictor or one interaction. For example, if there are three predictors (R,C,S), then all of the following predictors can be found in the model: R, C, S, R:C, R:S, C:S, R:C:S. Hence, we calculate the difference in SS of the full model with one predictor out of the seven predictors left out. In addition, to control the number of predictors in the interaction, the parameter highest_interaction_term is added to limit the number of predictors involved in an interaction. Using the example of three predictors, if highest_interaction_term=2, the predictors used in building the full model will only be R, C, S, R:C, R:S, C:S. The interaction term R:C:S will be excluded for it has 3 predictors which is not allowed in this case.
The calculation of the SS difference is then used to estimate how important the predictor that is left out is. To do this, F-tests are used. Using the example of two categorical predictors R with r levels, C with c levels, the following table will be generated for a dataset of n rows:
| Source | Degree of freedom | Model SS | Hypothesis | F |
|---|---|---|---|---|
| R | Coefficients for R are zero. | |||
| C | Coefficients for C are zero. | |||
| R:C Interaction | Coefficients for interaction R:C are zero. | |||
| Residual SS | of full model | |||
| Total: |
Finally, to answer the question that certain coefficients should be zero, we calculate the p-value from the F-tests just like the p-value calculation with a Gaussian distribution. In this case, we assume that the distribution of F is the F statistic. If the p-value calculated is small, you reject the hypothesis that the set of parameters associated with a predictor should be set to zero.
Examples
- R
- Python
library(h2o)
h2o.init()

# Import the prostate dataset:
train <- h2o.importFile("http://s3.amazonaws.com/h2o-public-test-data/smalldata/prostate/prostate_complete.csv.zip")

# Set the predictors and response:
x <- c("AGE", "VOL", "DCAPS")
y <- "CAPSULE"

# Build and train the model:
anova_model <- h2o.anovaglm(y = 'CAPSULE',
                            x = c('AGE','VOL','DCAPS'),
                            training_frame = train,
                            family = "binomial",
                            missing_values_handling="MeanImputation")

# Check the model summary:
summary(anova_model)
import h2o
h2o.init()
from h2o.estimators import H2OANOVAGLMEstimator

#Import the prostate dataset
train = h2o.import_file("http://s3.amazonaws.com/h2o-public-test-data/smalldata/prostate/prostate_complete.csv.zip")

# Set the predictors and response:
x = ['AGE','VOL','DCAPS']
y = 'CAPSULE'

# Build and train the model:
anova_model = H2OANOVAGLMEstimator(family='binomial',
                                   lambda_=0,
                                   missing_values_handling="skip")
anova_model.train(x=x, y=y, training_frame=train)

# Get the model summary:
anova_model.summary()
- Submit and view feedback for this page
- Send feedback about H2O-3 Secure to cloud-feedback@h2o.ai