Deployment options
H2O Hydrogen Torch offers three options to deploy a built model: you can deploy a built model using the H2O Hydrogen Torch user interface (UI) (1), the model's H2O MLOps pipeline (2), and a model's Python scoring pipeline (3).
Below, each option is explained in turn.
H2O Hydrogen Torch UI
You can score new data on built models (experiments) that generate downloadable predictions through the H2O Hydrogen Torch user interface (UI). To score new data through the H2O Hydrogen Torch UI, consider the following instructions:
- In the H2O Hydrogen Torch navigation menu, click Predict data.
- In the Experiment box, select the built experiment you want to use to score new data.
- In the Prediction Name box, enter a name for your prediction.
- In the Dataset, Prediction, and Environment settings section, define the display settings.
Note
Display settings will depend on the problem type of the selected built model (experiment). See Prediction settings to learn about the settings.
- Click Run predictions.
Note
- After running your predictions, H2O Hydrogen Torch will take you to the View predictions card, where you can view running and completed predictions. To learn more, see View a prediction.
- To download the generated predictions through the H2O Hydrogen Torch UI, see Download a prediction.
Explore the following tutorial to learn how to deploy a model through the H2O Hydrogen Torch UI: Tutorial 1B: Model deployment through the H2O Hydrogen Torch UI.
H2O MLOps pipeline
H2O Hydrogen Torch allows you to download an H2O MLOps scoring pipeline of a built model that you can use to score new data using the H2O MLOps REST API.
Explore the following tutorial to learn how to deploy a model using the model's H2O MLOps pipeline: Tutorial 2B: Model deployment with a model's H2O MLOps pipeline.
Download H2O MLOps Pipeline
To download the H2O MLOps pipeline of a built model, consider the following instructions:
- In the H2O Hydrogen Torch navigation menu, click View experiments.
- In the View experiments table, select the name of the experiment (model) you want to download its H2O MLOps Pipeline.
Note
- An H2O MLOps pipeline is only available for an experiment with a finished status.
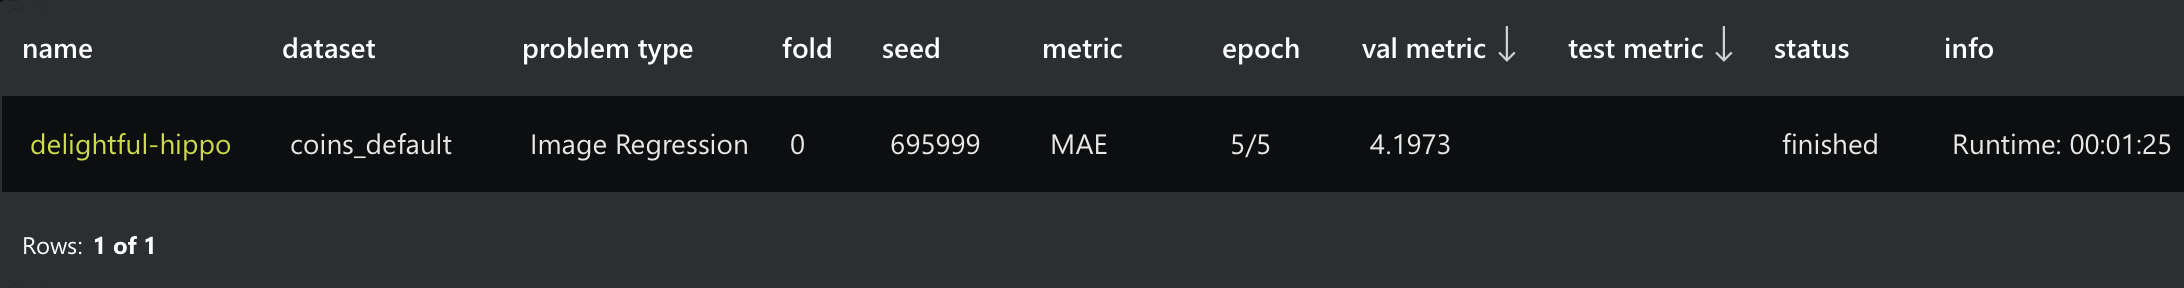
- To learn about all the different experiment statuses, see Experiment statuses.
- An H2O MLOps pipeline is only available for an experiment with a finished status.
- Click Download MLOps.
Note
The downloaded H2O MLOps pipeline, contains the following files:
- api_pipeline.py: an example Python script demonstrating how to score new data using an MLOps API endpoint
- model.mlflow.zip: a .zip file container (model) ready to be uploaded to H2O MLOps for deployment
- README.txt: a README file that contains information about the other files in the folder
Deploy model
Consider the following sequential steps to deploy a model using the model's H2O MLOps pipeline:
-
Select a built model
-
Download the MLOps Pipeline
-
Deploy the MLFlow model to H2O MLOps
NoteThe MLFlow model comes inside the downloaded H2O MLOps pipeline (model.mlflow.zip).
-
You can score new data by using the endpoint URL of your deploy model in H2O MLOps. The downloaded H2O MLOps pipeline includes sample code in the
api_pipeline.pyfile.Details
api_pipeline.py
import base64import jsonimport cv2import requests# fill in the endpoint URL from MLOpsURL = "enpoint_url"# if you want to score an image, please base64 encode it and send it as stringimg = cv2.imread("image.jpg")input = base64.b64encode(cv2.imencode(".png", img)[1]).decode()# in case of text, you can simply send the stringinput = "This is a test message!"# json data to be sent to APIdata = {"fields": ["input"], "rows": [[input]]}# for text span prediction problem type, pass question and context texts# input = ["Input question", "Input context"]# data = {"fields": ["question", "context"], "rows": [input]}# post requestr = requests.post(url=URL, json=data)# extracting data in json formatret = r.json()# read output, output is a dictionaryret = json.loads(ret["score"][0][0])NoteThe received JSON response from an H2O MLOps REST API call follows the same format as the
.pklfiles discussed on the follwing page: Download a prediction. -
Monitor requests and predictions on H2O MLOps (i.e., Granfana)
Python scoring pipeline
H2O Hydrogen Torch allows you to download a Python scoring pipeline of a built model that you can use to score new data in any external Python environment.
Explore the following tutorial to learn how to deploy a model using the model's Python scoring pipeline: Tutorial 3B: Model deployment with a model's Python scoring pipeline.
Download Python scoring pipeline
To download a model's Python scoring pipeline, consider the following instructions:
- In the H2O Hydrogen Torch navigation menu, click View experiments.
- In the View experiments table, select the name of the experiment (model) you want to download its Python scoring pipeline.
Note
- A Python scoring pipeline is only available for experiments with a finished status.
- To learn about all the different experiment statuses, see Experiment statuses.
- A Python scoring pipeline is only available for experiments with a finished status.
- Click Download scoring.
Note
The downloaded Python scoring pipeline, contains the following files:
- hydrogen_torch-*.whl: a wheel package containing the necessary H2O Hydrogen Torch framework functionality to generate predictions
- scoring_pipeline.py: an example Python script demonstrating how to load the model and score new data
- README.txt: a README file that contains information about the other files in the folder
- checkpoint.pth: checkpoint of trained model
- cfg.p: internal hydrogen_torch config file
- images: a folder containing sample images from the validation dataset
- audios: a folder containing sample audios from the validation dataset
- texts: a folder containing sample texts from the validation dataset
Deploy model
Consider the following sequential steps to deploy a model using the model's Python scoring pipeline:
-
Select a built model
-
Download the model's Python scoring pipeline
-
Install the H2O Hydrogen Torch wheel package in a Python 3.8 environment of your choice
Note- A fresh environment is highly recommended and can be set up using
pyenvorconda. For more information, see Pyenv or Managing Conda environments - The H2O Hydrogen Torch Python scoring pipeline only supports Ubuntu 16.04+ with Python 3.8
- Ensure that Python 3.8-dev is installed for Ubuntu versions that support it. To install it, run
sudo apt-get install python3.8-dev - Update setuptools (
pip install --upgrade pip setuptools) and pip (pip install --upgrade pip) - For audio models you need to install the following dependencies:
sudo apt-get install libsndfile1 ffmpeg
- Ensure that Python 3.8-dev is installed for Ubuntu versions that support it. To install it, run
- The H2O Hydrogen Torch
.whlpackage is shipped with the downloaded Python scoring pipeline- To install the
.whlpackage, runpip install hydrogen_torch-*.whl
- To install the
- A fresh environment is highly recommended and can be set up using
-
Run the
scoring_pipeline.pyfile (which contains sample code to score new data using your trained model weights)Details
scoring_pipeline.py
# Copyright (c) 2022 H2O.ai. Proprietary License - All Rights Reserved"""scoring pipeline for models trained in H2O Hydrogen Torch."""import globimport jsonimport osimport dillimport pandas as pdfrom torch.utils.data import DataLoader, SequentialSamplerfrom hydrogen_torch.src.utils.modeling_utils import (load_checkpoint,run_python_scoring_inference,)# reading the config from trained experimentwith open("cfg.p", "rb") as pickle_file:cfg = dill.load(pickle_file)# changing internal cfg settings for inference, not subject to changecfg.prediction._calculate_test_metric = False# preparing examplary dataframe for inference loading samples# this has to be altered for custom data# Image data -------------------------------------------------------if hasattr(cfg.dataset, "image_column"):images = []for image in sorted(glob.glob("images/*")):images.append(os.path.basename(image))test_df = pd.DataFrame({f"{cfg.dataset.image_column}": images})# set image foldercfg.dataset.data_folder_test = "images"# ------------------------------------------------------------------# Audio data -------------------------------------------------------if hasattr(cfg.dataset, "audio_column"):audios = []for audio in sorted(glob.glob("audios/*")):audios.append(os.path.basename(audio))test_df = pd.DataFrame({f"{cfg.dataset.audio_column}": audios})# set audio foldercfg.dataset.data_folder_test = "audios"# ------------------------------------------------------------------# Text data --------------------------------------------------------if hasattr(cfg.dataset, "text_column"):texts = []for text in sorted(glob.glob("texts/*")):texts.append(open(text).read())test_df = pd.DataFrame({f"{cfg.dataset.text_column}": texts})# special handling for span prediction problem typeif all(hasattr(cfg.dataset, column) for column in ("question_column", "context_column")):questions_and_contexts = []for text in sorted(glob.glob("texts/*")):data = json.load(open(text))questions_and_contexts.append({cfg.dataset.question_column: data["question"],cfg.dataset.context_column: data["context"],})test_df = pd.DataFrame.from_dict(questions_and_contexts)# ------------------------------------------------------------------# set device for inferencecfg.environment._device = "cuda:0"# disable original pretrained weights for model initializationif hasattr(cfg.architecture, "pretrained"):cfg.architecture.pretrained = False# it is possible to specify a custom cache directory for Huggingface transformers modelsif hasattr(cfg, "transformers_cache_directory"):cfg.transformers_cache_directory = None# loading model and checkpointmodel = cfg.architecture.model_class(cfg).eval().to(cfg.environment._device)cfg.architecture.pretrained_weights = "checkpoint.pth"load_checkpoint(cfg, model)# preparing torch dataset and dataloader# batch_size and num_workers are subject to changebatch_size = 1 if cfg.training._single_sample_inference_batch else 16test_dataset = cfg.dataset.dataset_class(df=test_df, cfg=cfg, mode="test")test_dataloader = DataLoader(test_dataset,sampler=SequentialSampler(test_df),batch_size=batch_size,num_workers=4,pin_memory=True,collate_fn=cfg.dataset.dataset_class.get_validation_collate_fn(),)# running actual inference# raw_predictions is a dictionary with predictions in the raw format# df_predictions is a pandas DataFrame with predictionsraw_predictions, df_predictions = run_python_scoring_inference(cfg=cfg, model=model, dataloader=test_dataloader)# final outputprint(df_predictions.head())
- Submit and view feedback for this page
- Send feedback about H2O Hydrogen Torch to cloud-feedback@h2o.ai